
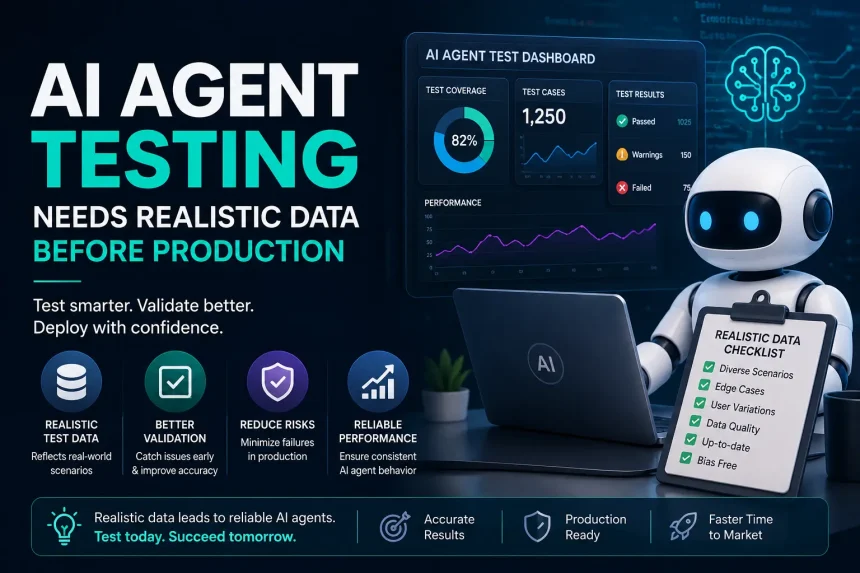
An AI agent can look impressive in a controlled demo and still fall apart when real users start interacting with it. A support agent may handle a clean question perfectly, then misunderstand a typo, follow an unexpected conversation path, or call the wrong tool when several conditions collide. That is why AI agent testing needs more than synthetic happy-path examples. Before an agent reaches production, it needs realistic data that reflects the messy, ambiguous, incomplete situations it will actually encounter.
Read more: CMF Buds Neo Review 2026: Price, Specs, Features and More
Why Does AI Agent Testing Need Realistic Data?
Traditional software testing often starts with clearly defined inputs and expected outputs. AI agents are different. Their behavior can depend on conversation history, retrieved information, tool responses, model reasoning, user intent, and the state of external systems.
Consider an AI customer-support agent. A basic test might ask:
“Where is my order?”
The expected response is straightforward. But real customers might say:
“Hey, my package was supposed to come yesterday and tracking hasn’t moved since Monday. Can you check what’s happening?”
Now the agent has several jobs. It needs to understand the intent, identify the relevant order, retrieve current information, interpret the tracking status and communicate an appropriate response.
Real users also make mistakes. They change their minds, provide incomplete information, use slang, repeat themselves and occasionally ask questions that have nothing to do with the original conversation.
A realistic test dataset captures those conditions.
The Difference Between a Demo and Production
A successful demonstration usually proves that an agent can complete a task.
Production testing needs to determine whether it can complete that task consistently under varied conditions.
That’s a much harder problem.
An agent might successfully process 100 carefully written test prompts while failing when users:
- Use misspellings or abbreviations.
- Give contradictory information.
- Change their request halfway through a conversation.
- Ask several questions at once.
- Provide incomplete details.
- Refer to something mentioned many messages earlier.
- Trigger multiple tools during one workflow.
- Ask the agent to perform an action it isn’t authorized to perform.
These aren’t unusual edge cases. They are normal human behavior.
What Makes Data “Realistic” for AI Agent Testing?
Realistic doesn’t necessarily mean copying an entire production database into a test environment. It means reproducing the patterns, variability and constraints that an agent is likely to encounter.
A useful test dataset should represent the different ways people interact with the system.
Include Different User Behaviors
Suppose you’re testing an AI sales agent.
A simplistic dataset might contain questions such as:
- “What is the price?”
- “Do you offer annual plans?”
- “Can I cancel?”
A more realistic dataset could include:
- “How much would this cost for 20 employees?”
- “I don’t want the annual plan. What happens if I cancel after three months?”
- “We need something for our US and UK teams. Does the same plan cover both?”
- “I saw a different price yesterday—why did it change?”
The second group is much closer to what an actual sales conversation looks like.
Model Messy Inputs
Typos, shorthand and incomplete sentences should have a place in the test suite.
For example:
“need refund asap order 4481”
A good agent shouldn’t require grammatically perfect English to understand the request.
The same applies to multilingual users, regional terminology and industry-specific vocabulary when those are relevant to the product.
How Can Realistic Data Expose Agent Failures?
One of the biggest benefits of realistic test data is that it reveals failures that aren’t obvious from individual responses.
An AI agent is often part of a larger workflow. It may need to retrieve information, call APIs, update records, ask for confirmation and then produce a final response.
A mistake at any stage can produce a bad outcome.
Test the Entire Workflow
Imagine an agent designed to process expense claims.
The intended workflow might be:
User request → Extract expense details → Check policy → Verify receipt → Calculate eligible amount → Ask for approval → Update system
Testing only the final answer misses important failure points.
What happens if:
- The receipt image is unreadable?
- The currency isn’t specified?
- The amount exceeds the employee’s limit?
- The expense category is ambiguous?
- The approval system is unavailable?
- The user submits the same claim twice?
Realistic data helps reproduce these conditions before customers encounter them.
Tool-Calling Needs Special Attention
Tool use is one of the areas where AI agents differ from ordinary chatbots.
An agent might have access to a CRM, payment system, database, calendar or internal knowledge base. Testing should therefore evaluate not only what the agent says, but also what actions it takes.
For example, if a customer asks to cancel a subscription, the agent shouldn’t simply produce a convincing confirmation message. The underlying cancellation action must happen correctly, with appropriate authorization and safeguards.
A polished response can hide a dangerous workflow failure.
What Types of Realistic Test Data Should Teams Build?
There isn’t one universal dataset that works for every AI agent. The right test data depends on the agent’s job, users and risk level.
Still, several categories are useful across projects.
1. Normal Cases
These represent common user requests and establish a baseline.
Examples include routine support questions, ordinary product searches or straightforward scheduling requests.
2. Edge Cases
Edge cases deliberately push the system toward less common scenarios.
For example:
- Extremely long conversations
- Missing fields
- Conflicting instructions
- Unusual product names
- Multiple simultaneous requests
- Unexpected tool failures
3. Adversarial Cases
Agents also need testing against attempts to manipulate their behavior.
These may include prompt injection, instruction conflicts, unauthorized requests and attempts to make the agent disclose information it shouldn’t reveal.
Security testing should be treated as part of the overall evaluation process rather than an afterthought.
4. Historical and Representative Cases
When privacy and governance requirements allow it, de-identified historical interactions can be extremely valuable.
They show how real users actually communicate—not how developers imagine they communicate.
That difference can be surprisingly large.
How Should Teams Protect Realistic Data?
Realistic doesn’t mean careless.
Using production information directly in a testing environment can create privacy, security and compliance problems. Personal information, payment details, confidential business information and credentials should never be copied into test systems without appropriate controls.
Use De-Identification and Controlled Synthetic Data
A practical approach is to create test datasets that preserve the structure and behavior of real interactions without exposing sensitive information.
For example, instead of using a real customer:
“Rahul, customer ID 829174, ordered…”
a test record might use:
“Customer A, synthetic ID 10482, ordered…”
The goal is to preserve the scenario, not the person’s identity.
Synthetic data can also be useful when teams need thousands of variations. But generated examples should be reviewed carefully. Poor synthetic data often becomes too neat, repetitive or unrealistic.
A useful test set usually combines carefully designed synthetic scenarios with appropriately governed real-world patterns.
How Do You Measure AI Agent Performance?
Testing becomes much more useful when teams define measurable criteria before running the evaluation.
Accuracy is only one part of the picture.
For an AI agent, teams may evaluate:
- Task success: Did the agent accomplish the user’s actual goal?
- Tool accuracy: Did it call the correct tool with the correct parameters?
- Groundedness: Were claims supported by available information?
- Safety: Did the agent avoid unauthorized or harmful actions?
- Consistency: Does it behave reliably across similar scenarios?
- Escalation: Does it hand difficult cases to a human when appropriate?
- Latency: Does it respond quickly enough for the intended experience?
- Cost: Is the workflow economically practical at scale?
This is where AI agent evaluation becomes more meaningful than simply checking whether an answer “sounds good.”
Build a Regression Test Set
Once a failure is discovered, don’t simply fix it and move on.
Turn that failure into a permanent test case.
Over time, the test suite becomes a record of what the agent has previously gotten wrong. Every new model, prompt, retrieval system or tool integration can then be evaluated against those known failure modes.
That creates a much stronger development cycle:
Test → Find failure → Fix → Add regression case → Retest
It’s simple, but extremely effective.
Why Production-Like Testing Should Happen Before Launch
The final testing environment should resemble production as closely as practical.
That includes realistic prompts, representative conversation lengths, relevant tool responses, retrieval conditions and expected system failures.
An agent that works beautifully with a clean test database may behave differently when information is incomplete or stale.
Likewise, an agent tested only with short conversations may struggle when users return to a topic after 20 or 30 messages.
Production-like testing gives teams a chance to discover those weaknesses while they are still inexpensive to fix.
Don’t Wait for Production to Find the Edge Cases
There is a natural temptation to launch quickly and “learn from real users.”
For low-risk applications, limited releases and monitoring can be reasonable. But for agents that can make purchases, modify records, access confidential information or make consequential decisions, relying on production users as the primary test environment is a poor strategy.
The cost of a failed AI interaction isn’t always another incorrect sentence. It could be a duplicated payment, deleted record, incorrect booking or privacy incident.
Testing should happen before those consequences are possible.
Frequently Asked Questions
Why is realistic data important for AI agent testing?
Realistic data exposes ambiguity, incomplete information, unusual phrasing, tool failures and complex workflows that clean test prompts often miss. It gives teams a better picture of how an AI agent may behave under real operating conditions.
Is synthetic data enough for testing AI agents?
Synthetic data is useful for generating controlled variations and covering scenarios that are difficult to collect safely. However, purely synthetic datasets can be overly clean, so representative real-world patterns are valuable when privacy and governance requirements permit.
What should an AI agent test dataset include?
A strong dataset can include normal requests, edge cases, adversarial prompts, incomplete information, multi-turn conversations, tool failures and realistic workflow scenarios. The exact mix should reflect the agent’s users and risk profile.
How can companies test AI agents without exposing customer data?
Organizations can use de-identified examples, privacy-safe transformations, synthetic records and controlled test environments. Sensitive information such as credentials, payment data and unnecessary personal identifiers should be excluded from testing datasets.
Conclusion
AI agent testing is only as useful as the situations being tested. Clean prompts and predictable workflows may prove that an agent works in ideal conditions, but production rarely looks ideal.
Realistic data introduces the ambiguity, interruptions, incomplete information, tool failures and unexpected requests that agents will encounter outside the lab. Combined with measurable evaluations, regression testing and appropriate privacy controls, it gives development teams a much stronger basis for deciding whether an agent is ready for production.
The goal isn’t to predict every possible user interaction. That’s impossible. The goal is to expose enough realistic failure modes before launch that the remaining risks are understood, measurable and manageable.